 Merciven
Hospital data platform
Ingestion, masking and dbt transformation for six US hospitals on Databricks and Snowflake.
- Organisation
- Benttella Consulting LLC (US, remote)
- My role
- Data Engineer
- When
- 2026
- Stack
- Databricks, Snowflake, dbt, PySpark
Problem statement
Each hospital sent data in its own format and schedule, and patient identifiers had to be masked before anyone downstream could use the data.
Objectives & goals
- Onboard a new hospital by configuration, not new code
- Mask personal data before it leaves the raw layer
- Give analysts consistent, tested models
- Catch bad data before it reaches reports
Process
- DiscoverProfiled each hospital's feeds and their quirks.
- DefineConfig tables for sources and QA rules; data contracts for outputs.
- BuildConfig-driven bronze ingestion, masking, silver merges, dbt gold models on Iceberg.
- ProveQA gates that stop the job, contract checks and reconciliation against legacy output.
Who it's for
Needs the same numbers from every hospital.
Needs proof personal data is masked.
Challenges
- Six hospitals, six formats
- Patient data under strict access rules
- Silent type drift breaking downstream tables
What I built
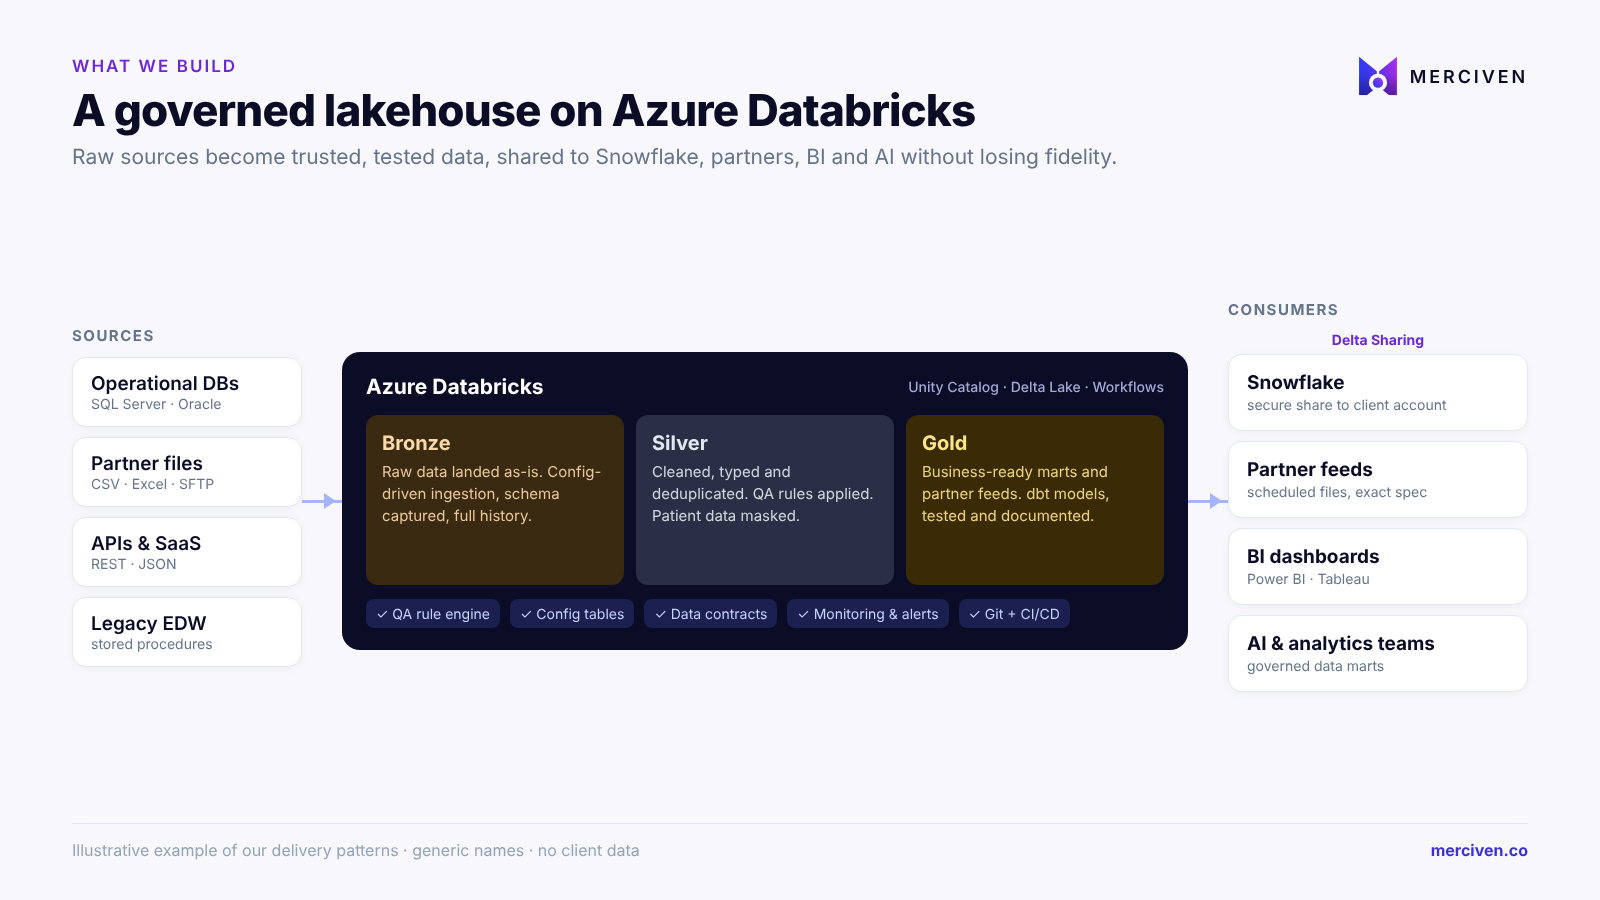
One generic pipeline reads a sources table.
Hashed keys, initials and masked emails before silver.
A failed error rule stops the job before bad data spreads.
Block type drift such as decimal(38,2) to decimal(38,6).
Flow
- Hospital feeds
- Config-driven bronze
- QA rules
- Silver MERGE
- Mask PII
- dbt gold on Iceberg
- Contract check
- Analytics
Screens
Results
Tools & languages
The code
A complete Databricks demo on synthetic data: config-driven ingestion, QA rules, masking, data contracts and reconciliation.
The repository is private. I'm happy to share it with a hiring team or walk you through it on a call.
Request a code walkthrough · Read the other healthcare data engagements
Samples are written with synthetic data. No client code or client data is used.