Work

Case studies

A selection of data engineering projects. Client names, data and identifying details are withheld under confidentiality agreements.

Client
A global pharmaceutical company
Industry
Pharmaceuticals
Stack
Azure Databricks, Snowflake, Delta Sharing, SQL, Python

Governed data delivery for a global pharmaceutical brand

The challenge

The client’s commercial and partner teams needed custom data views built to strict specifications, and data had to move between Databricks and Snowflake with column names, data types and precision exactly preserved.

What we did

  • Lead the data engineering team on the account, owning sprint planning, estimation and delivery
  • Built custom views in Azure Databricks to partner specifications and delivered them to production
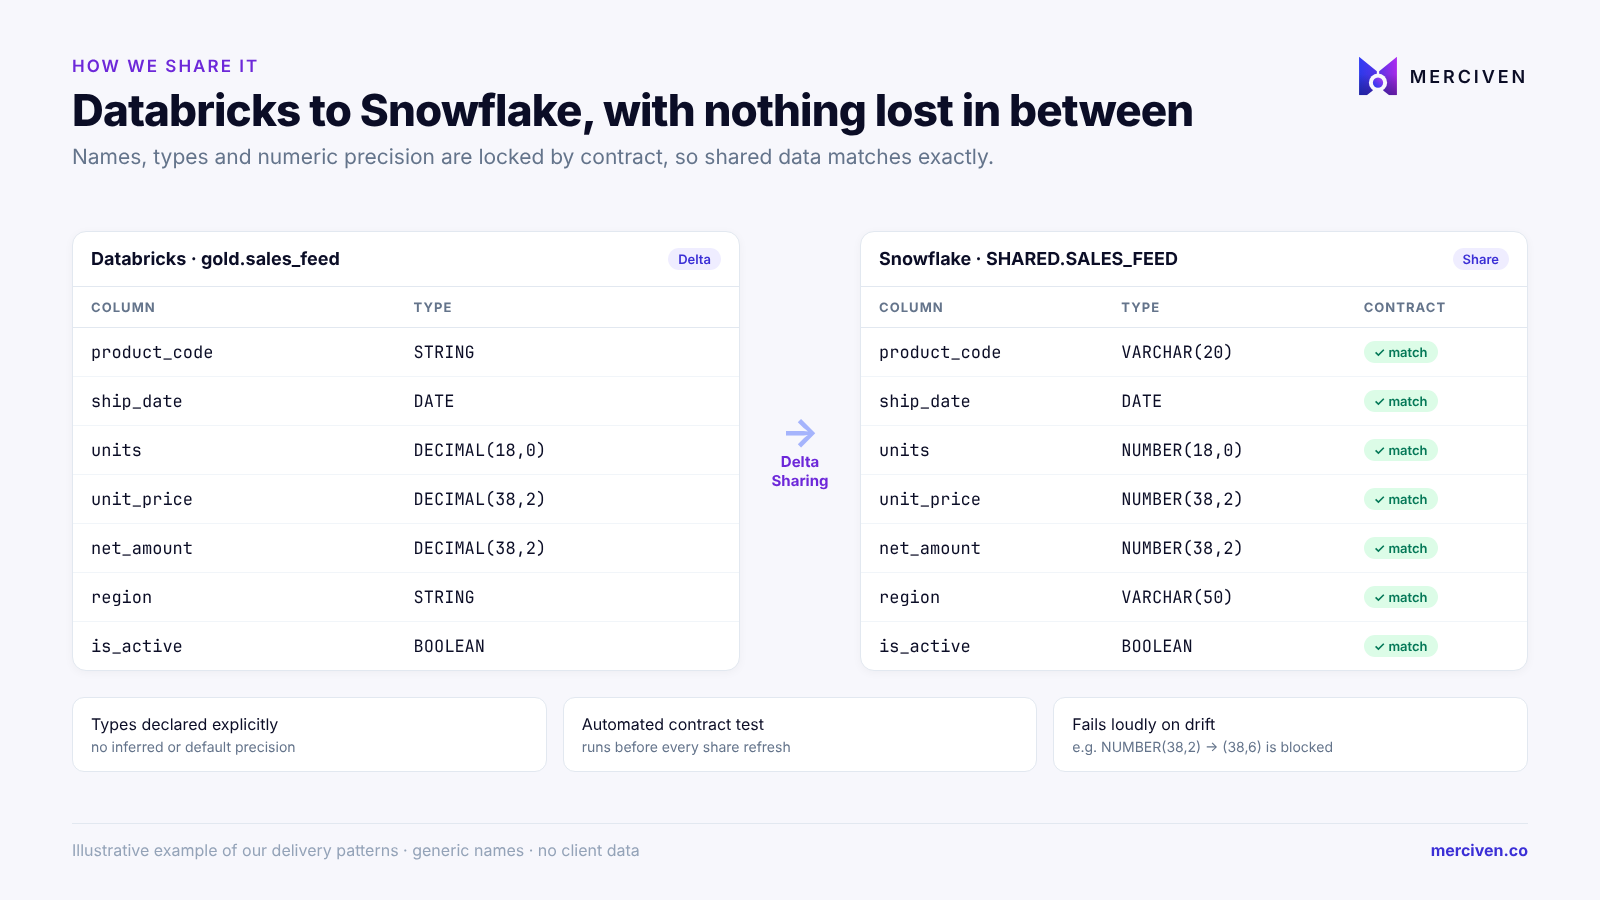
  • Built cross-platform data sharing from Databricks to Snowflake with explicit data contracts, so types and precision never drift
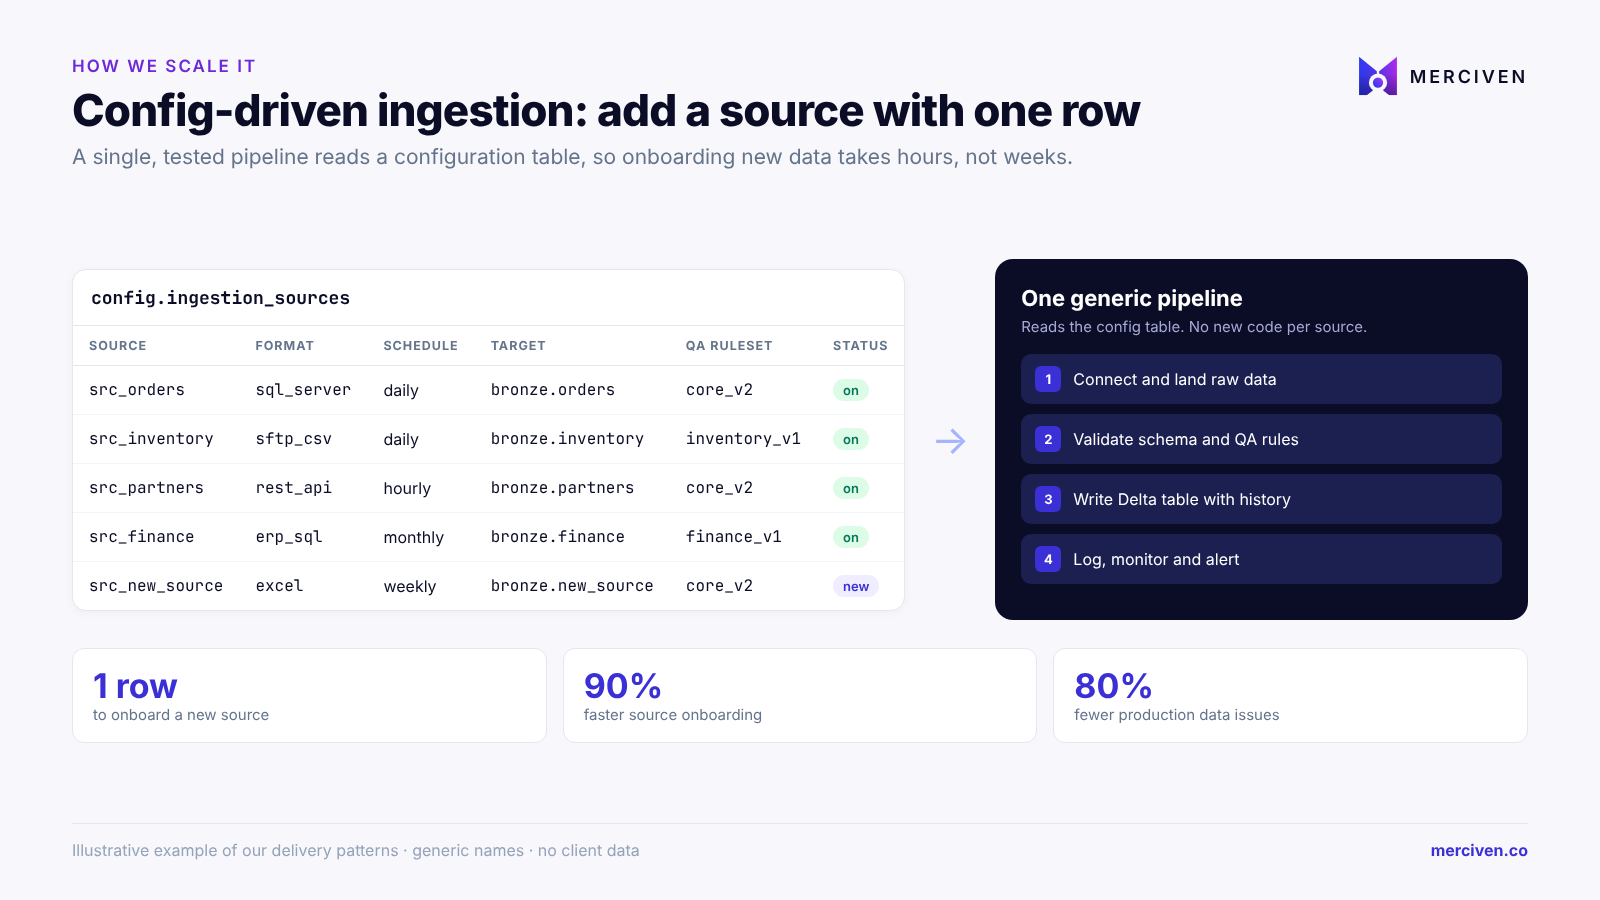
  • Built configuration-driven ingestion with automated QA rules for new data
  • Built data marts that feed the client’s AI and reporting teams

The outcome

Partner and analytics teams receive governed, specification-exact data from one platform, shared directly across Databricks and Snowflake.
Client
A US healthcare data services provider
Industry
Healthcare · specialty pharmacy
Stack
Azure Databricks, Snowflake, SQL, Python, Git

Specialty pharmacy data feeds for pharmaceutical manufacturers

The challenge

Pharmaceutical manufacturers depend on scheduled feeds of inventory, dispense and regulatory programme data. The feeds ran on legacy stored procedures and needed to move to a modern platform with identical output.

What we did

  • Built and shipped daily, weekly and monthly data feeds to production on Azure Databricks
  • Migrated legacy stored procedures to parameterised Databricks notebooks, with output reconciled against the legacy files
  • Applied industry data standards and formatting rules required by manufacturers
  • Took ownership of handed-over feeds and trained engineers to support them

The outcome

Manufacturers receive reliable, on-schedule feeds from a modern, maintainable platform in production.

Client
A US healthcare provider network
Industry
Healthcare · hospitals
Stack
Databricks, Snowflake, dbt, Apache Iceberg, SQL, Python

A unified data platform for a multi-hospital network

The challenge

Patient and operational data arrived from several hospitals in different formats. It had to be combined, standardised and masked before analysts could use it, without exposing sensitive information.

What we did

  • Built ingestion and masking workflows for data from every hospital in the network
  • Developed dbt models and YAML source configurations to standardise transformation across sources
  • Built and managed Apache Iceberg tables on Databricks and Snowflake
  • Ran daily production processing for the whole network

The outcome

One consistent, masked data layer that analysts across the network can query, with transformation logic defined once in dbt instead of repeated per hospital.

Client
A data analytics platform
Industry
Software & analytics
Stack
Azure, Databricks, Python, SQL

A metadata-driven ingestion framework

70%lower ingestion latency
90%faster source onboarding
80%fewer production data issues

The challenge

Every new client data source needed a hand-written pipeline. Onboarding was slow, latency was high and schema changes in source data regularly broke production.

What we did

  • Replaced one-off pipelines with a metadata-driven framework on Azure and Databricks, so new sources are added through configuration
  • Optimised the ingestion path to reduce end-to-end latency
  • Added schema validation and automated monitoring at the point of ingestion

The outcome

Ingestion latency fell by about 70%, onboarding a new client or source became about 90% faster, and production data issues dropped by about 80%.

Client
A manufacturing company in West Africa
Industry
Manufacturing
Stack
Python, SQL, workflow automation, BI

Automating operational data for a manufacturer

80% → 10%share of the daily workload done by hand

The challenge

Production and operational data was collected and combined by hand every day. Most of the team’s time went into compiling reports instead of acting on them.

What we did

  • Mapped the existing workflows and found where data was re-entered or copied
  • Built a centralised system that collects and processes operational data automatically
  • Delivered management reporting and process monitoring on top of the new data

The outcome

The share of daily work done manually fell from about 80% to about 10%, and managers got consistent, timely reports on production activity.

How we build

Patterns from our Databricks and Snowflake work

Illustrative examples of how we build and run data platforms. Names are generic and no client data is shown.

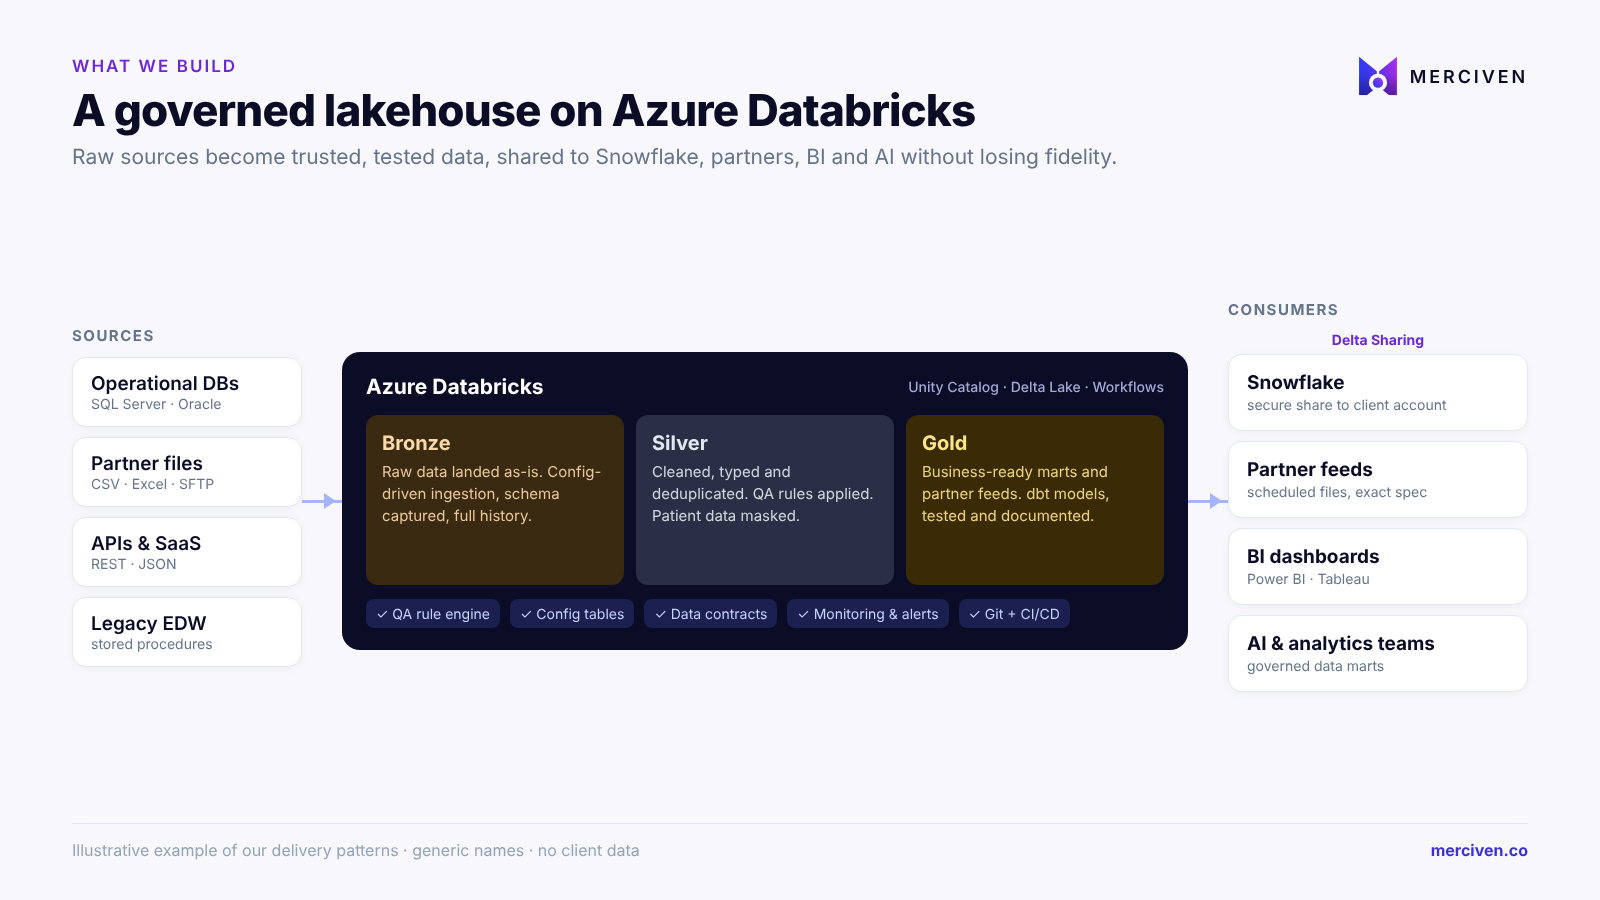
A governed lakehouse on Azure Databricks: Sources land in Bronze, are cleaned and masked in Silver, and published as tested Gold marts, then shared to Snowflake, partners, BI and AI.
A governed lakehouse on Azure Databricks. Sources land in Bronze, are cleaned and masked in Silver, and published as tested Gold marts, then shared to Snowflake, partners, BI and AI.
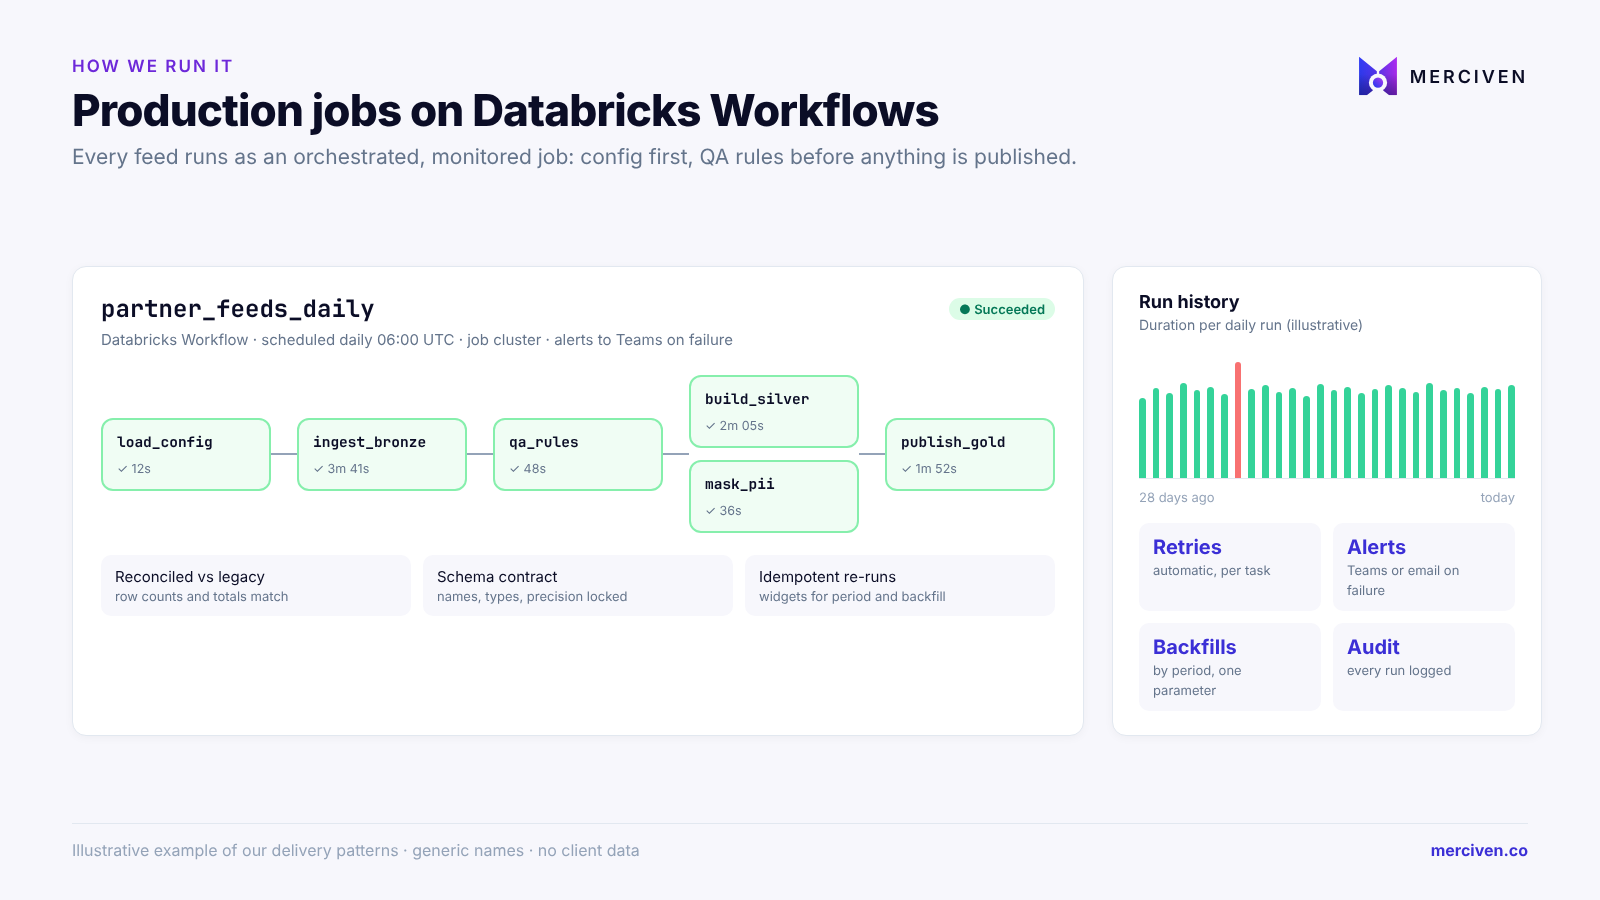
Production jobs on Databricks Workflows: Each feed runs as a scheduled, monitored job: configuration first, QA rules before anything is published, with retries, alerts and backfills.
Production jobs on Databricks Workflows. Each feed runs as a scheduled, monitored job: configuration first, QA rules before anything is published, with retries, alerts and backfills.
Databricks to Snowflake with locked data contracts: Column names, types and numeric precision are declared and tested, so shared data matches exactly.
Databricks to Snowflake with locked data contracts. Column names, types and numeric precision are declared and tested, so shared data matches exactly.
Config-driven ingestion: One tested pipeline reads a configuration table, so a new source is added with a row, not new code.
Config-driven ingestion. One tested pipeline reads a configuration table, so a new source is added with a row, not new code.

Want results like these?

Tell us what you are working on. We will tell you honestly whether we can help.

Book a call